[ChatStream] GPU Server Configurations for Large-Scale LLM Inference
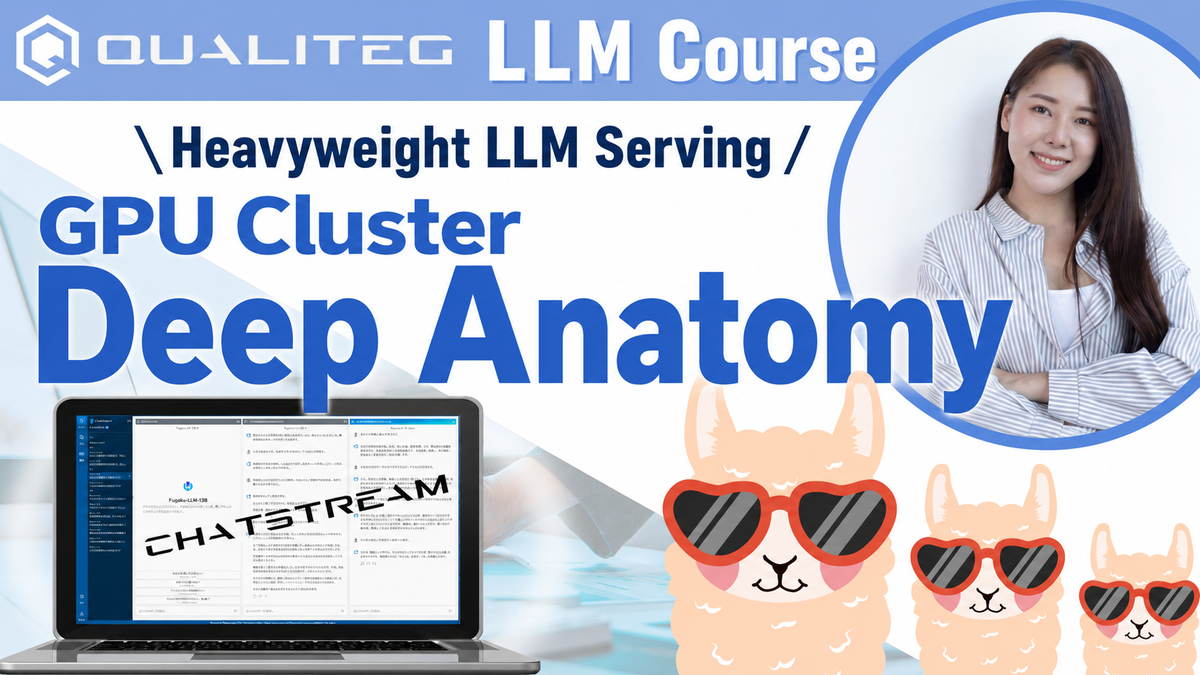
In this video, we take a detailed look at the GPU server configurations required for inference with large-scale LLMs (large language models) and how they work together with ChatStream.
Using the Llama3-70B model as an example, we explain its memory requirements (140 GB of GPU memory) and the GPU server and GPU cluster configurations needed to meet them, illustrated with the easy-to-work-with NVIDIA RTX A6000 GPU.
We also touch on model parallelization techniques (tensor parallelism, pipeline parallelism, and data parallelism) and the choice of inference engine, and show how a cluster built from multiple GPU servers actually performs inference efficiently.
Finally, we explain what a ChatStream LLM node is and how to scale it to handle large numbers of concurrent requests.
This video is especially useful for anyone interested in deploying and operating high-performance LLMs.